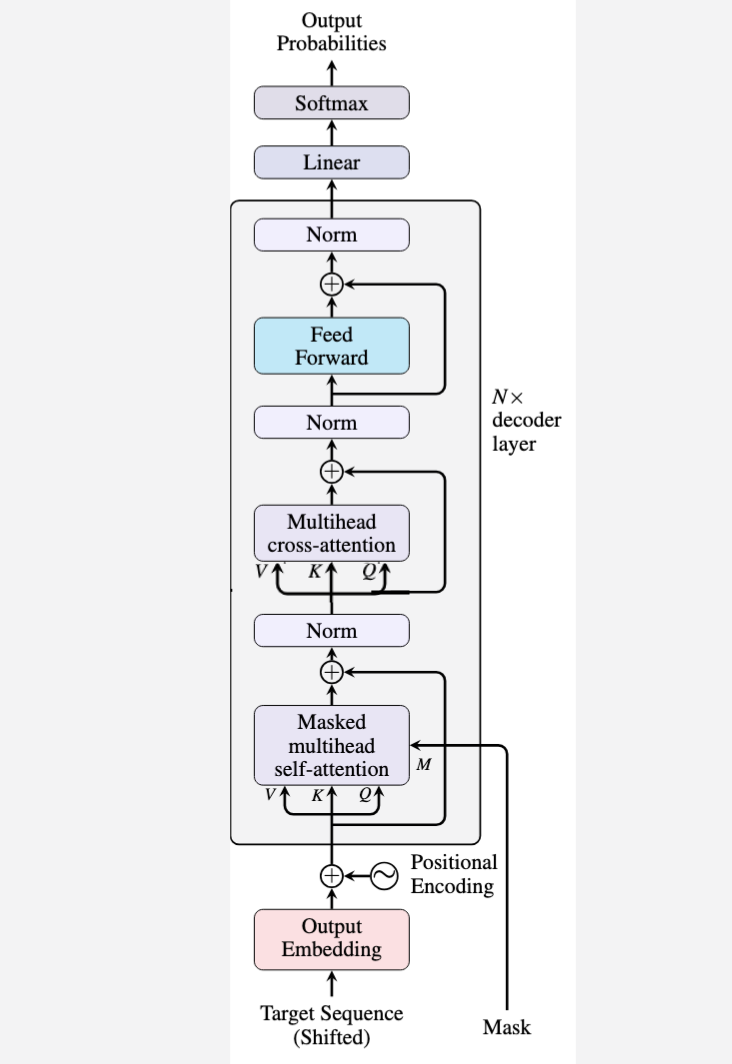
Decoder Stack Explained
- Shifted Target Sequence: Input tokens are shifted right to enable next-token prediction.
- Token Embedding + Positional Encoding: Converts discrete tokens into contextual vectors while preserving order.
- Masked Multi-Head Self-Attention: Prevents tokens from attending to future positions, enforcing causal generation.
- Add & Layer Normalization: Residual connections stabilize gradient flow and preserve earlier representations.
- Feed Forward Network (MLP Block): Applies non-linear transformations to enrich feature representations.
- N × Decoder Layers: The block is repeated multiple times to increase representational depth.
- Linear Projection + Softmax: Converts final hidden states into vocabulary probability distributions.
Minimal GPT Block (PyTorch Example)
This simplified GPT-style decoder block demonstrates masked self-attention and feed-forward processing.
import torch
import torch.nn as nn

class GPTBlock(nn.Module):
    def __init__(self, embed_dim=512, num_heads=8, ff_dim=2048):
        super().__init__()
        self.attn = nn.MultiheadAttention(embed_dim, num_heads, batch_first=True)
        self.ln1 = nn.LayerNorm(embed_dim)
        self.ff = nn.Sequential(
            nn.Linear(embed_dim, ff_dim),
            nn.GELU(),
            nn.Linear(ff_dim, embed_dim)
        )
        self.ln2 = nn.LayerNorm(embed_dim)

    def forward(self, x, mask):
        attn_output, _ = self.attn(x, x, x, attn_mask=mask)
        x = self.ln1(x + attn_output)
        ff_output = self.ff(x)
        x = self.ln2(x + ff_output)
        return x